研究
Extract Source-Backed Company Metadata
Extract website metadata candidates for one company domain with provenance.
下載工作流程
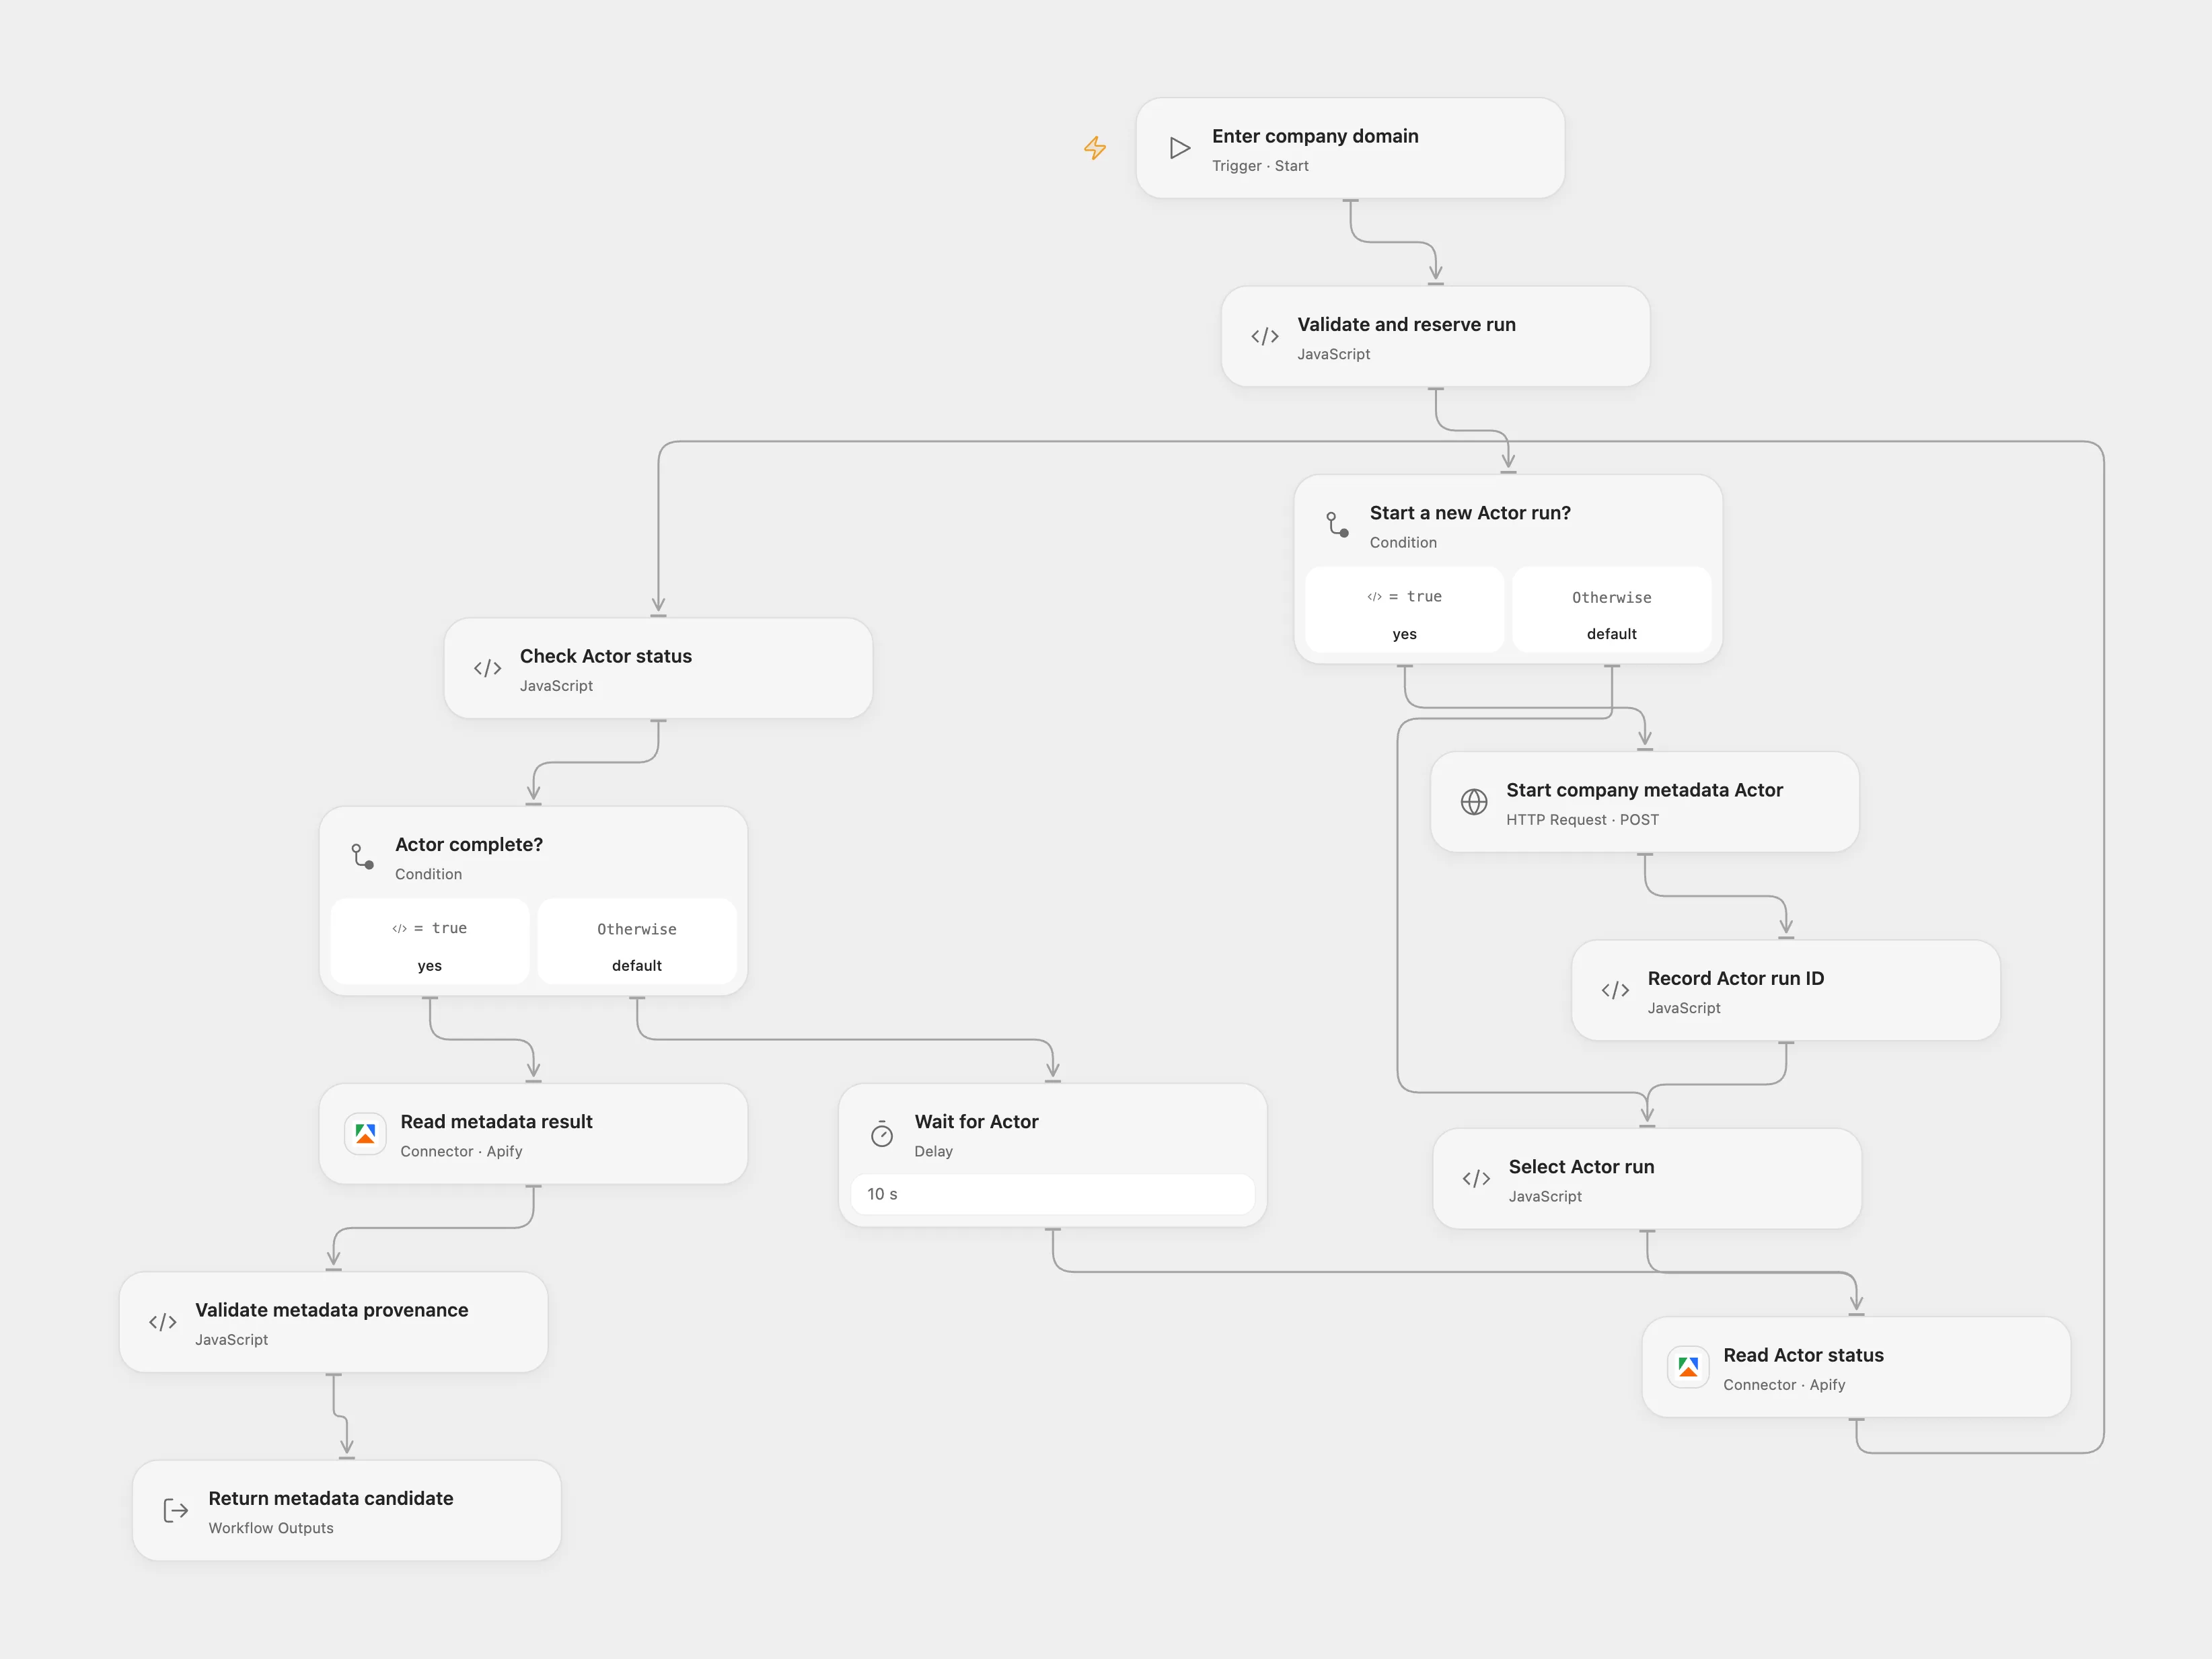
Extract website metadata candidates for one company domain with provenance.
Setup
Connect Apify and set APIFY_TOKEN to a token for the same account. Enter one bare domain and a unique request ID. Enable persistent State and prevent concurrent runs with the same ID.
Behavior
The Actor reads public website metadata and returns a single candidate only if the domain, integration source and scrape provenance match. Review candidates against authoritative sources before using them. The request retains the source limit of one result and maximum total charge of US$0.02; check current Actor pricing before use.
Open Flow starts the Actor asynchronously and resumes polling a recorded run ID for the same request. If start outcome is unknown, inspect Apify before resolving the pending State. No automatic launch retry is configured.
In n8n
In n8n, configure a Header Auth credential for Apify and set the domain, request ID and a Data Table with item_key and status columns. n8n uses the source synchronous endpoint; inspect Apify and its pending Data Table record if the response is uncertain before retrying.
Inspiration & credits
Adapted from Extract source-backed company website metadata with Apify in enescingoz/awesome-n8n-templates.
Source collection notice: © 2024–2026 Enes Cingoz, CC BY 4.0. The source export does not identify a separate template author or license. See repository licensing for the scope of OOMOL contributions and third-party material.