Get the details you need from web pages
Turn web pages into readable text and structured research material.
每月 20,000 次免費應用程式呼叫(付費服務另計)
應用程式介紹和工具詳情以英文提供。
可以做什麼
Read a page or a bounded set of pages, then extract the details relevant to your task. Useful outputs include product specifications, document outlines, and comparison tables with source URLs.
Collect page content
Keep the relevant headings and passages from a known webpage.
Extract a comparison table
Organize selected fields across pages while retaining a source URL for each row.
Find pages before extracting content
Map a site with search guidance and path filters, then extract the selected URLs.
Extract evidence for a specific question
Read selected URLs with an explicit research objective and retain the relevant passages.
Read a web page
Extract page text with Jina Reader.
可用服務
相關範本
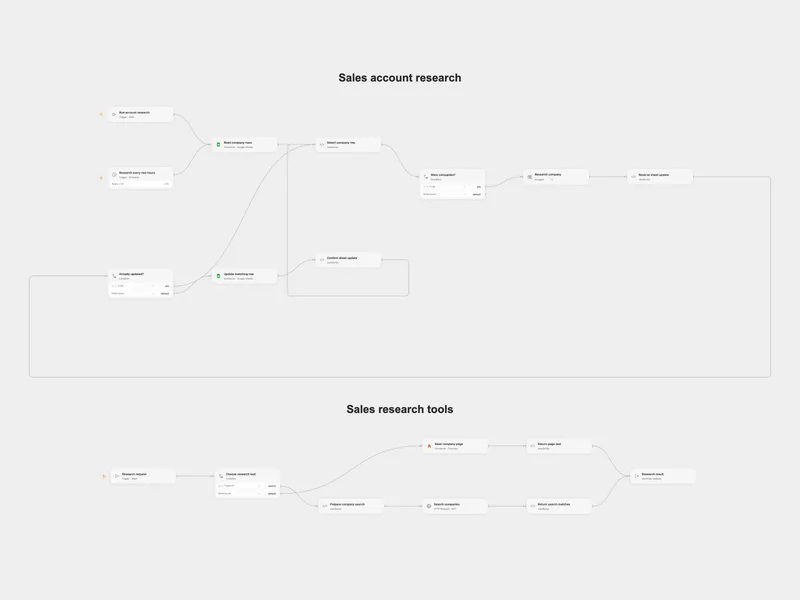
Research Sales Accounts in Google Sheets
Research companies on the web and update their matching spreadsheet rows.
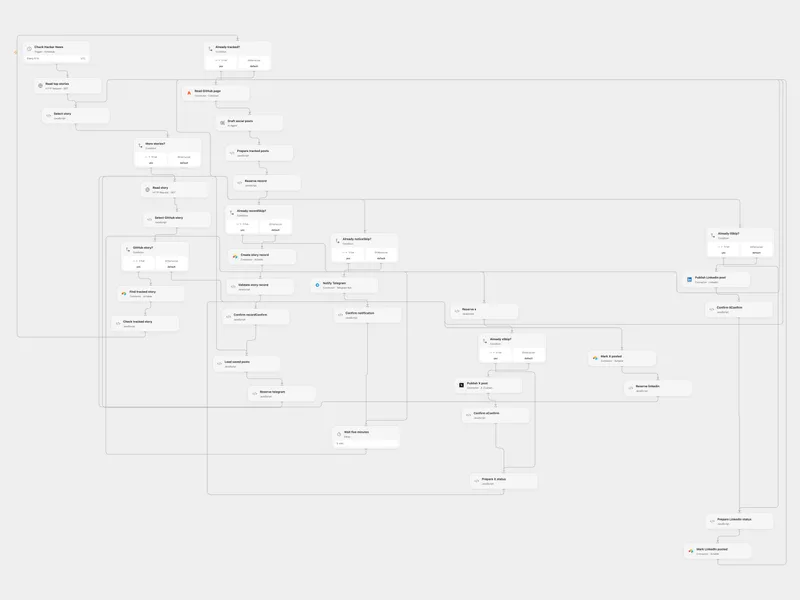
Amplify Hacker News GitHub Projects
Discover GitHub links on Hacker News, draft social posts and publish them after a short delay.
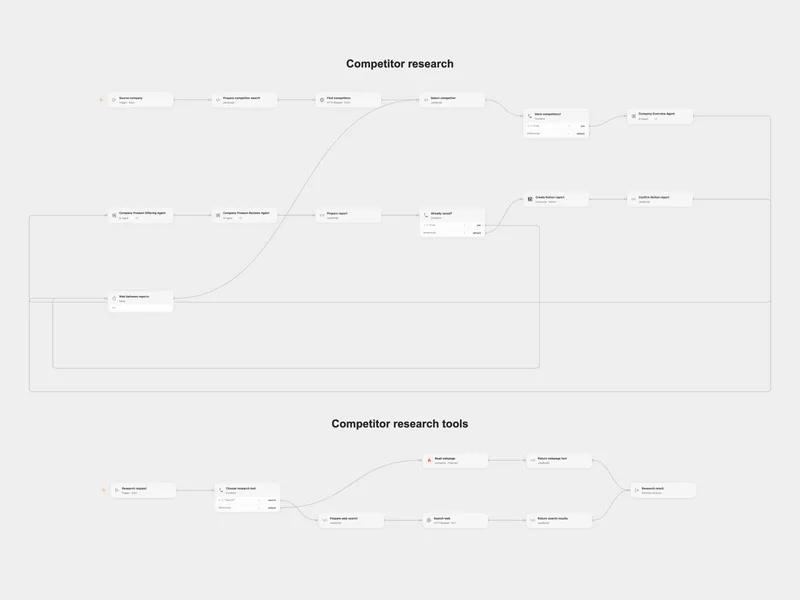
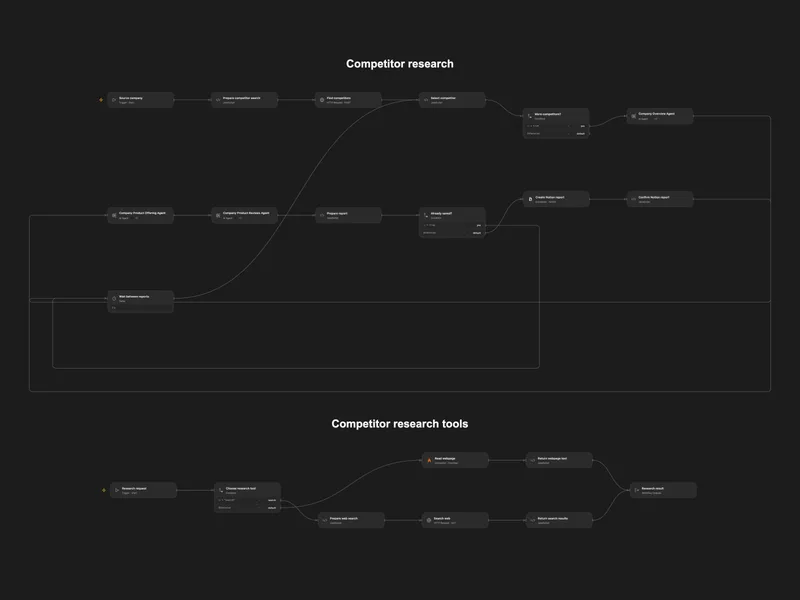
Research Competitors into Notion
Find competitors and research their company, products, and reviews in Notion.
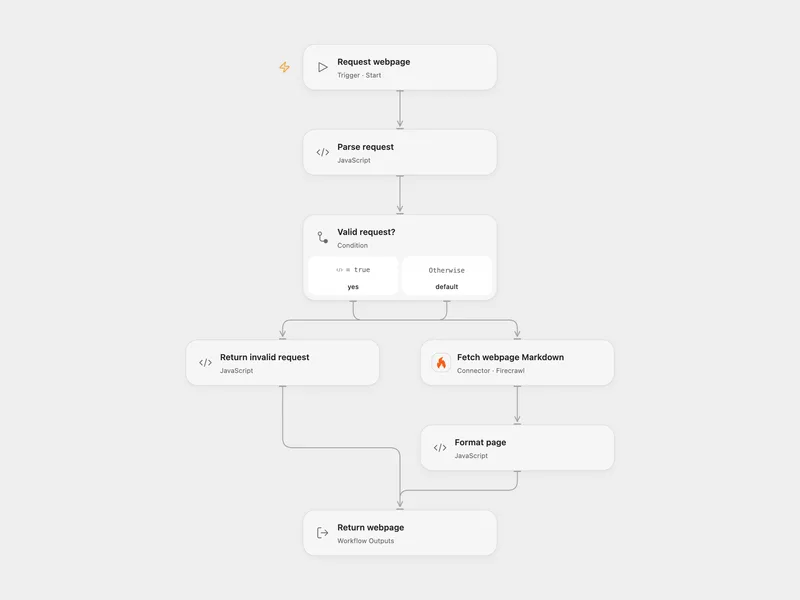
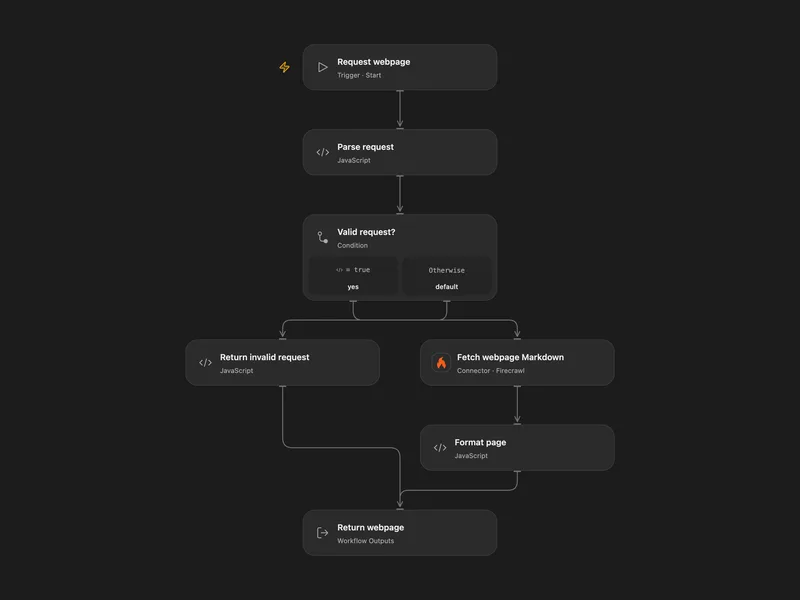
Fetch Webpage as Markdown
Fetch a webpage and return its Markdown content, optionally replacing links and image URLs.
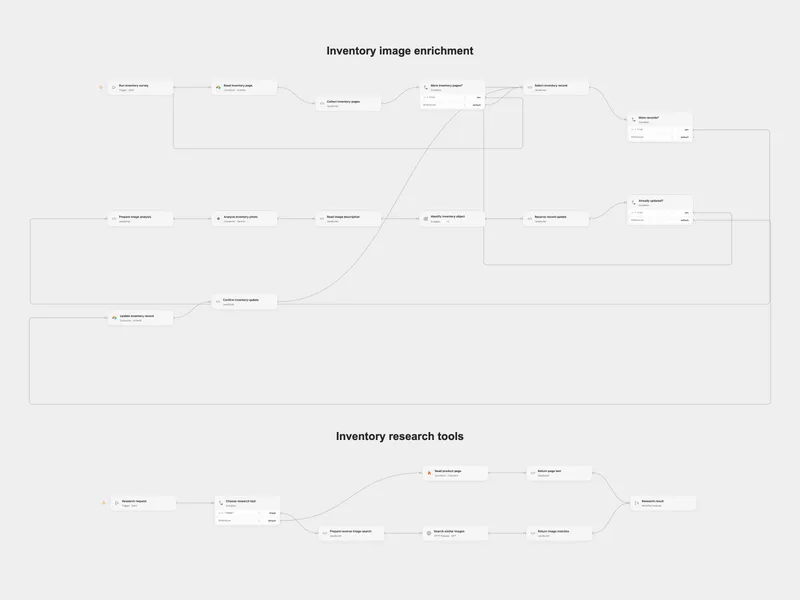
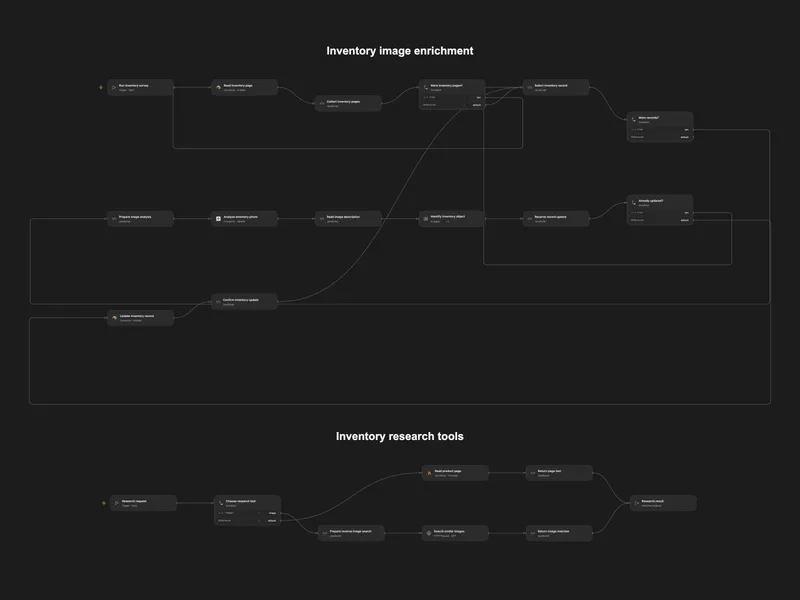
Enrich Property Inventory from Images
Analyze inventory photos and enrich Airtable records with product attributes.
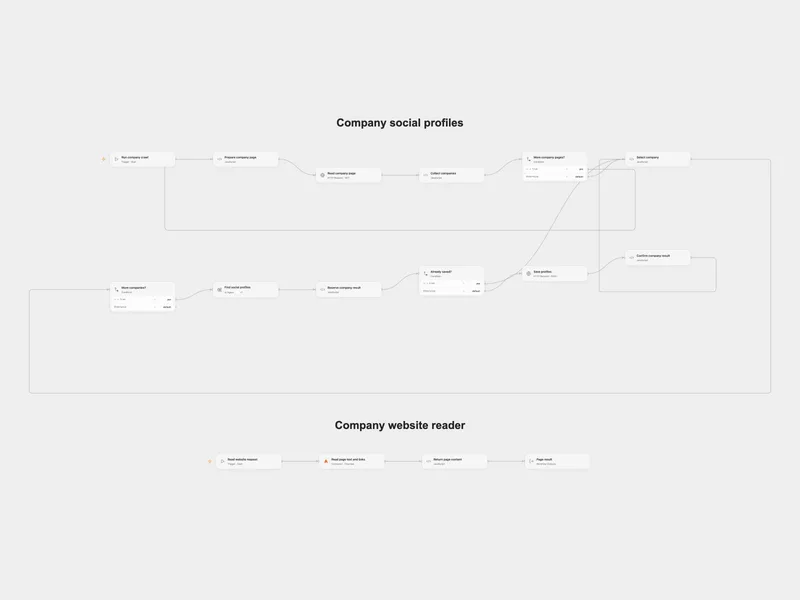
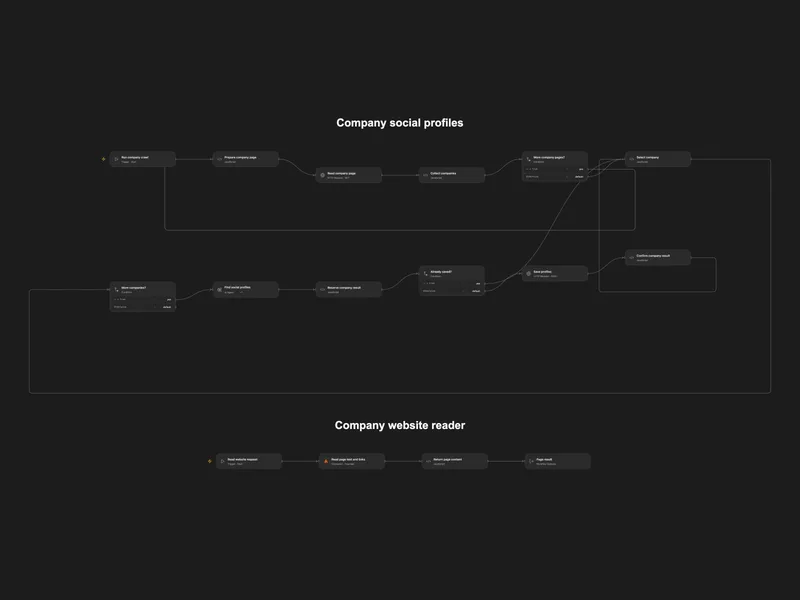
Crawl Company Social Profiles
Find company social profiles by exploring their websites and save the results to Supabase.
更多範本(5)
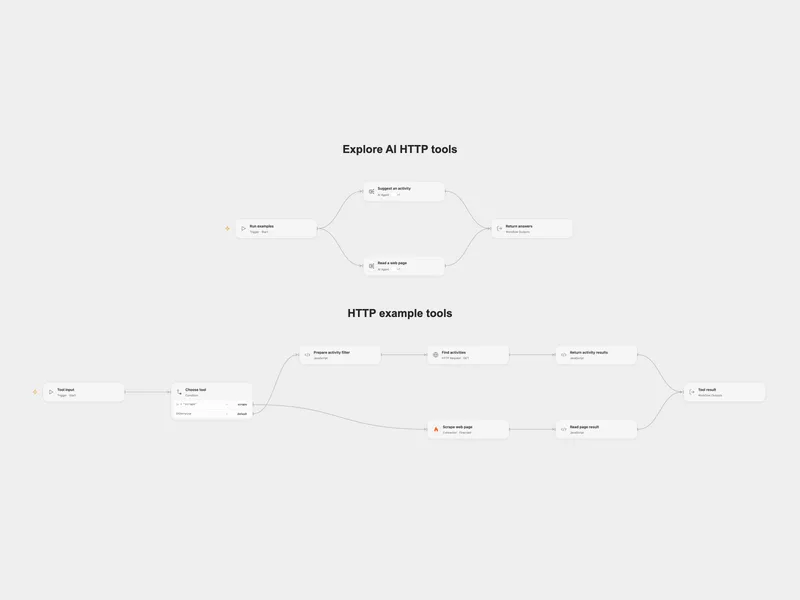
Explore AI HTTP Tools
Explore model-selected web scraping and activity search tools.
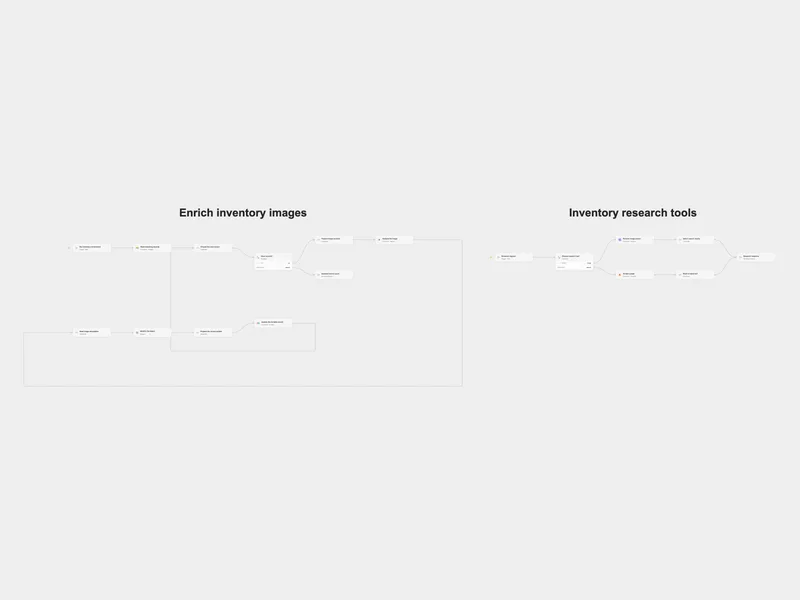
Enrich Airtable Inventory with Image Research
Research inventory images and update Airtable records with product attributes.
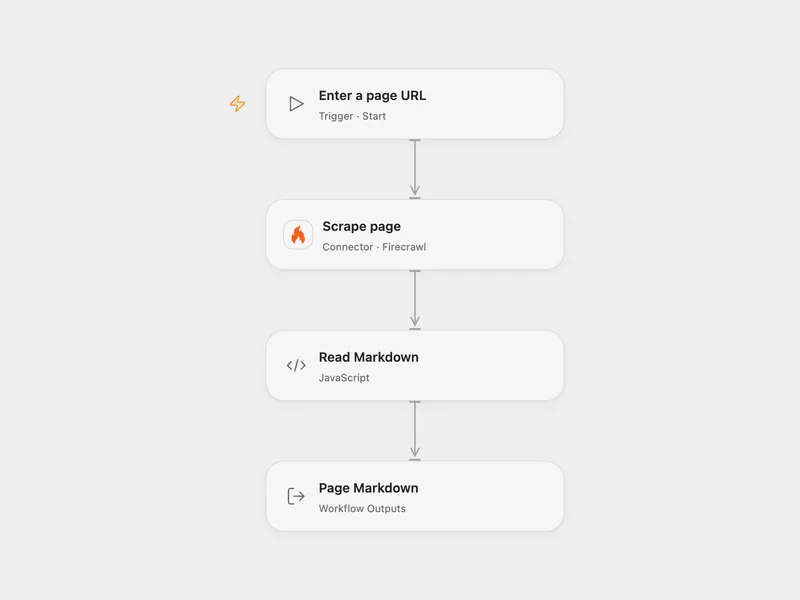
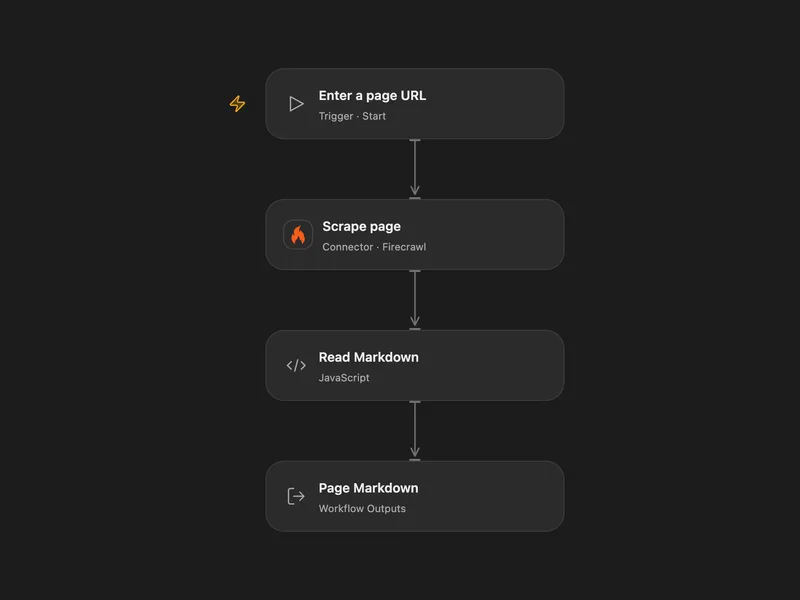
Scrape Page Markdown with Firecrawl
Call Firecrawl to scrape one page and return its Markdown.
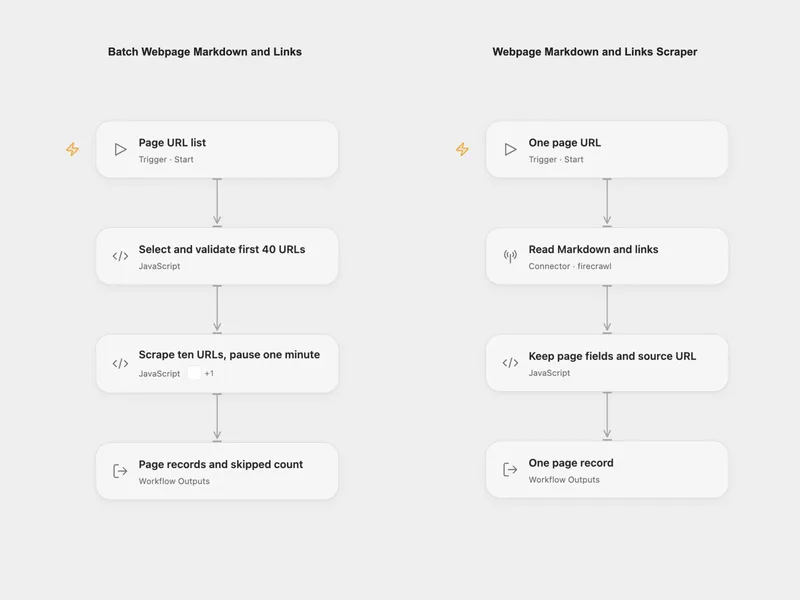
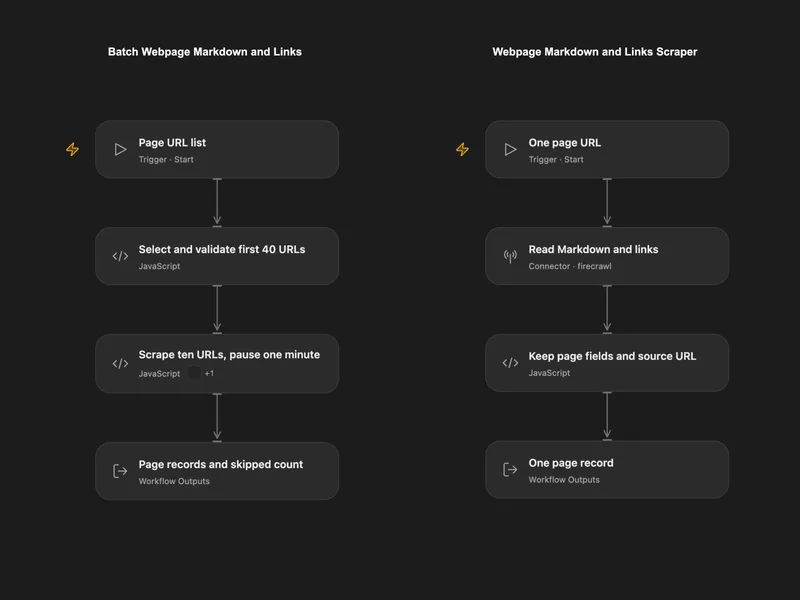
Batch Webpage Markdown and Links
Convert up to 40 page URLs into Markdown, metadata and link arrays, pausing one minute between groups of ten.
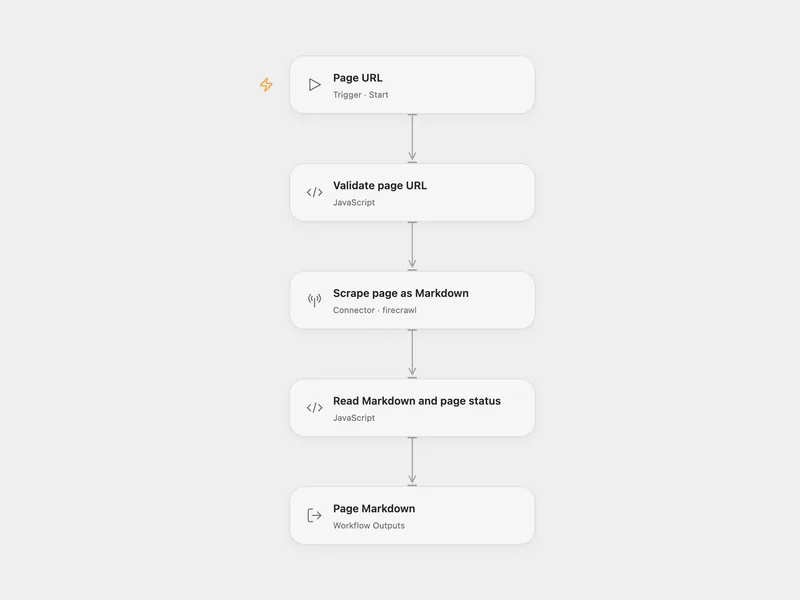
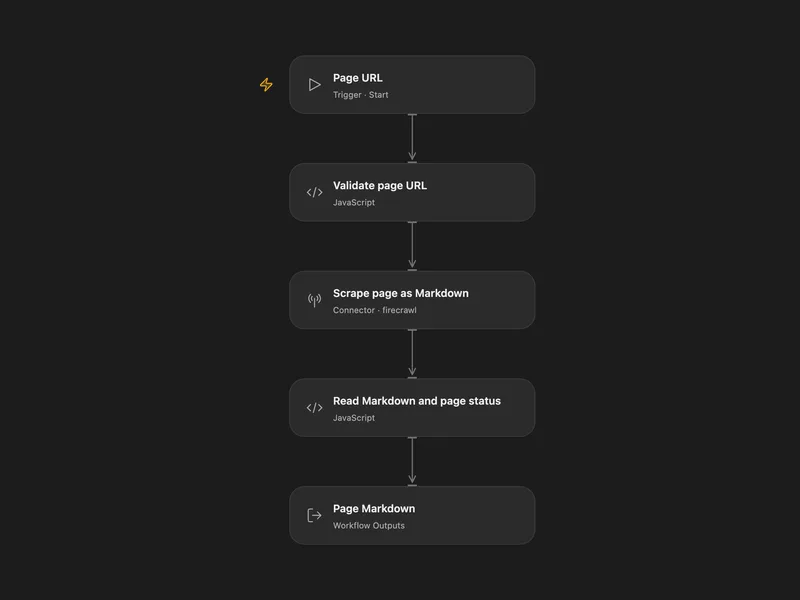
Webpage Markdown Extractor
Fetch one page through Firecrawl and return its Markdown content with the reported page status.
所有工具
Scrape Firecrawl
Retrieve one HTTPS web page as Markdown through Firecrawl. The AIsa route supports basic proxy mode and excludes PDF URLs.
aisa.scrape_firecrawlMap Firecrawl
Discover website links through Firecrawl. Set limit to bound discovery and usage before retrieving individual pages.
aisa.map_firecrawlScrape
Scrape a URL with Firecrawl or execute an enabled Alexandria provider tool and return the requested output formats.
firecrawl.scrapeMap Tavily
Discover site URLs using path and domain filters, crawl depth, and natural-language instructions.
aisa.map_tavilyExtract Tavily
Extract content from known URLs through Tavily. Inspect failed_results for per-URL failures; use crawl_tavily to discover and retrieve pages from a website.
aisa.extract_tavilyExtract Parallel
Extract relevant excerpts or full content from up to 20 URLs, guided by an objective and search terms. Return partial results and per-URL errors.
aisa.extract_parallelJina Reader Read
Read and extract URL content
fusion-api.jina_reader_read沒有符合搜尋條件的工具。