提取网页中需要的细节
将网页内容整理为可阅读文字与研究素材。
每月 20,000 次免费应用调用(付费服务另计)
可以做什么
读取单个网页或限定范围的网页集合,提取任务需要的细节,例如商品规格、文档提纲和带来源的对照表。
收集网页内容
从已知网页中保留相关标题与段落。
提取对照表
跨网页整理指定字段,为每行保留来源链接。
定位页面后提取内容
按搜索提示和路径筛选发现站点页面,再提取选定网址。
按问题提取网页依据
指定研究目标,从选定网页中提取相关段落。
读取网页正文
用 Jina Reader 提取网页正文。
可用服务
相关模板
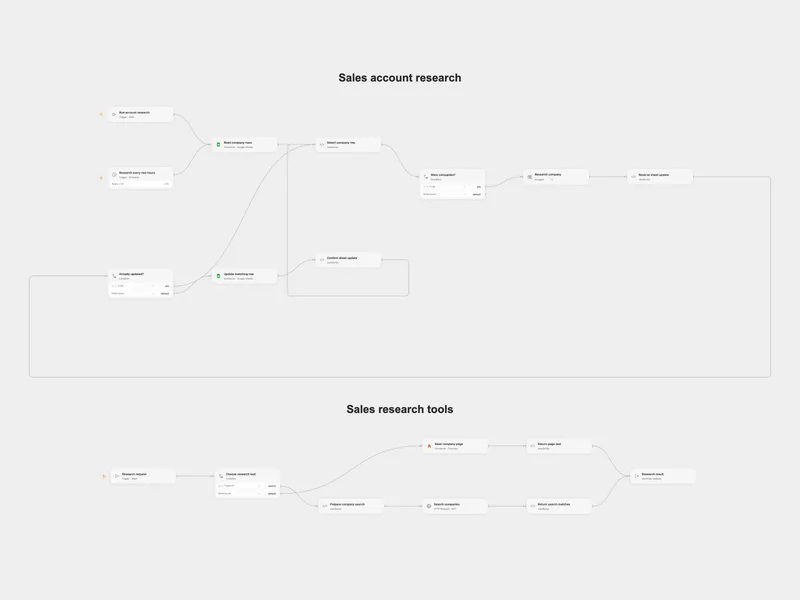
Research Sales Accounts in Google Sheets
Research companies on the web and update their matching spreadsheet rows.
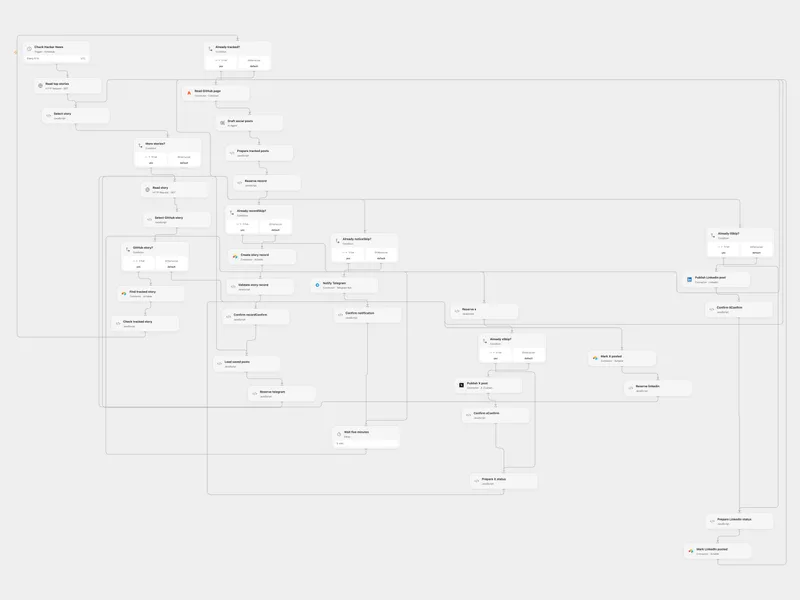
Amplify Hacker News GitHub Projects
Discover GitHub links on Hacker News, draft social posts and publish them after a short delay.
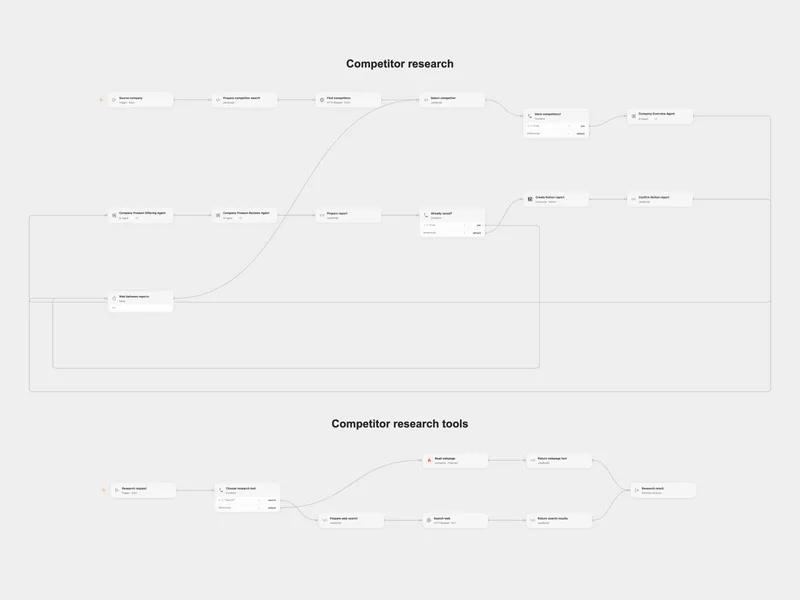
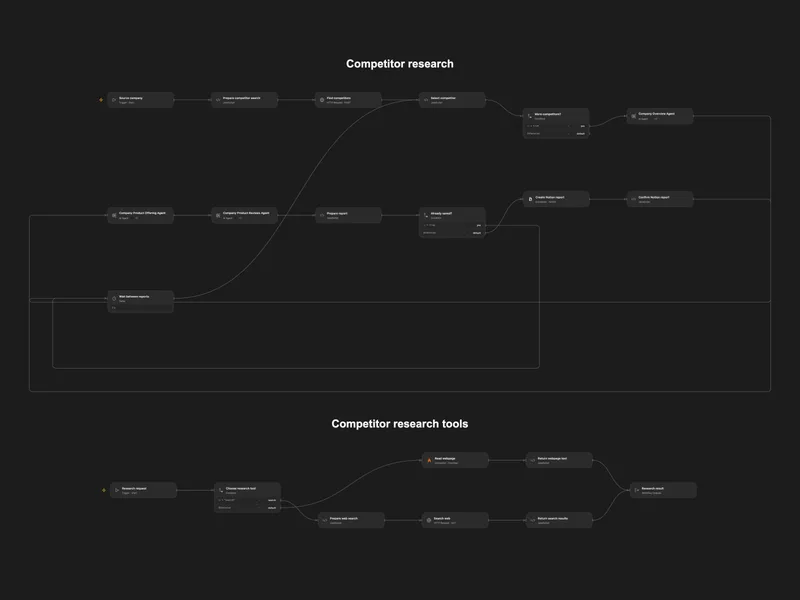
Research Competitors into Notion
Find competitors and research their company, products, and reviews in Notion.
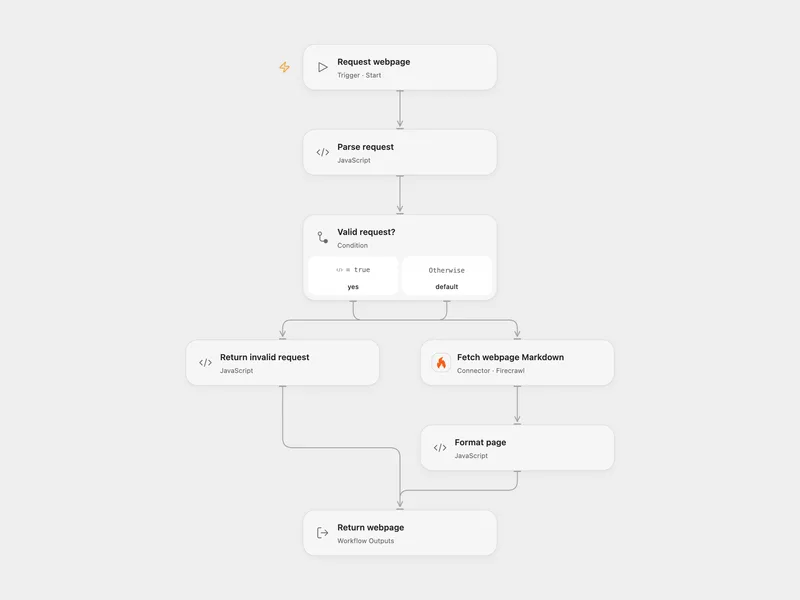
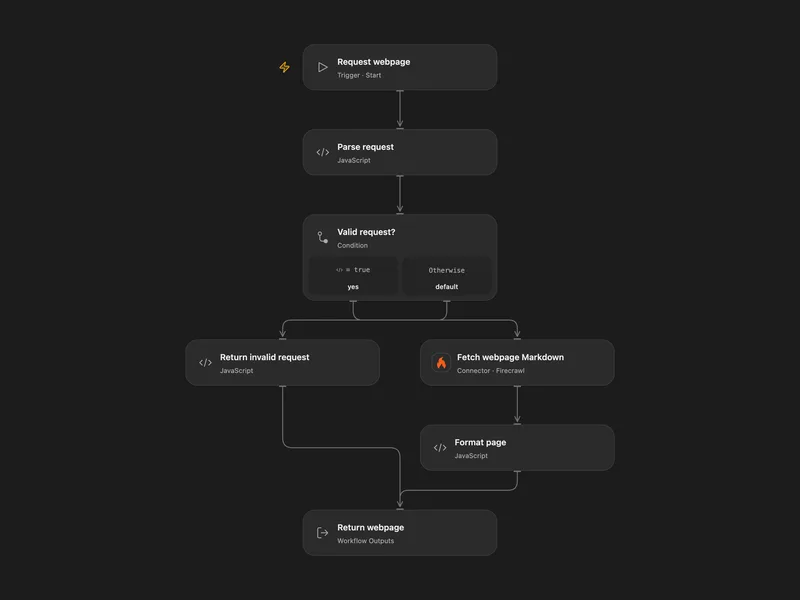
Fetch Webpage as Markdown
Fetch a webpage and return its Markdown content, optionally replacing links and image URLs.
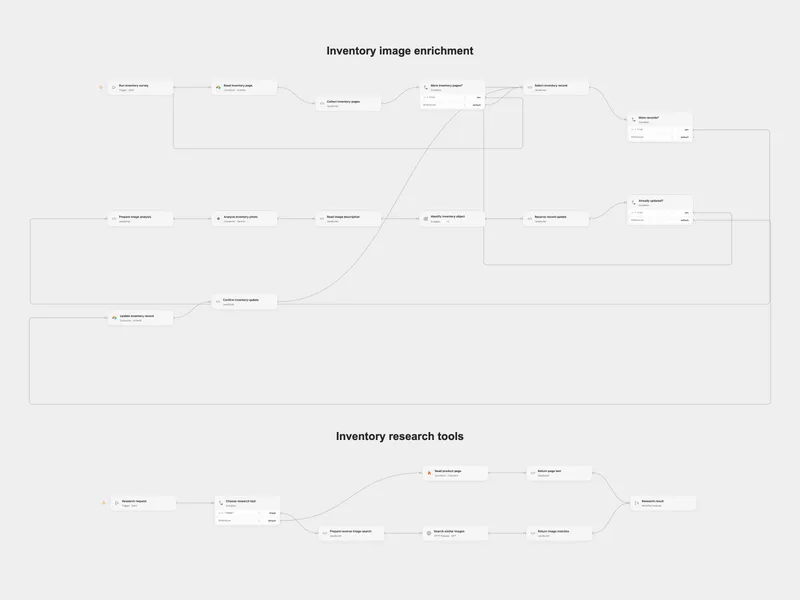
Enrich Property Inventory from Images
Analyze inventory photos and enrich Airtable records with product attributes.
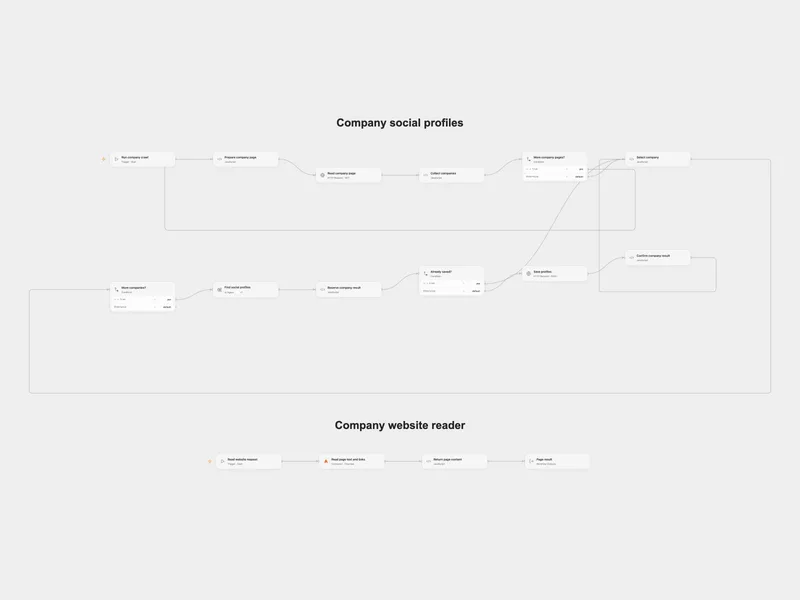
Crawl Company Social Profiles
Find company social profiles by exploring their websites and save the results to Supabase.
更多模板(5)
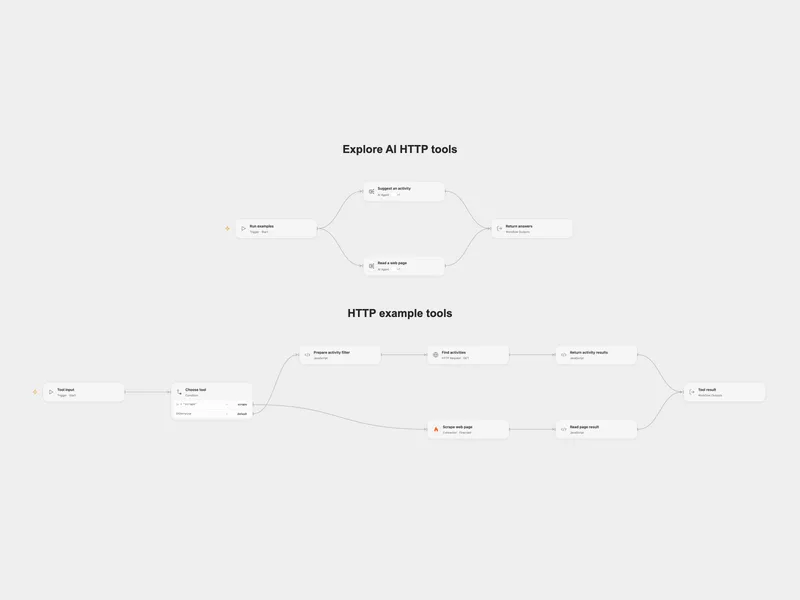
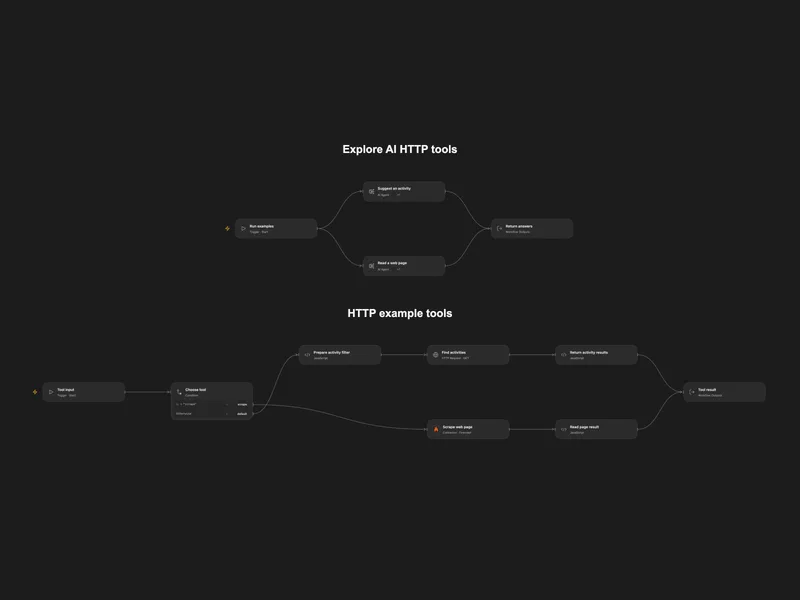
Explore AI HTTP Tools
Explore model-selected web scraping and activity search tools.
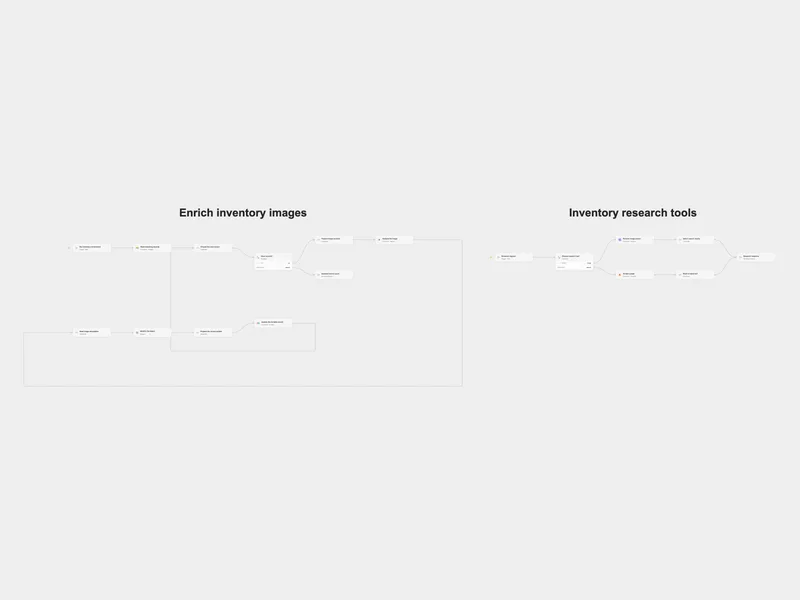
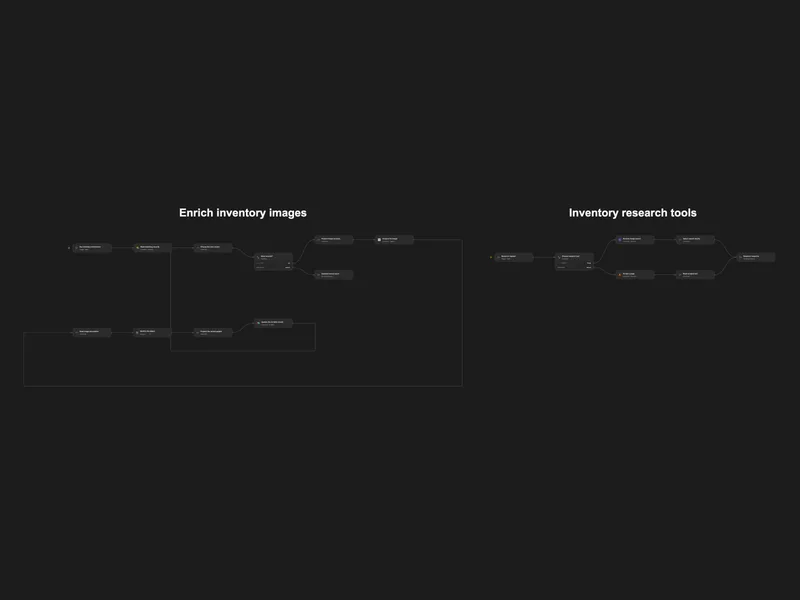
Enrich Airtable Inventory with Image Research
Research inventory images and update Airtable records with product attributes.
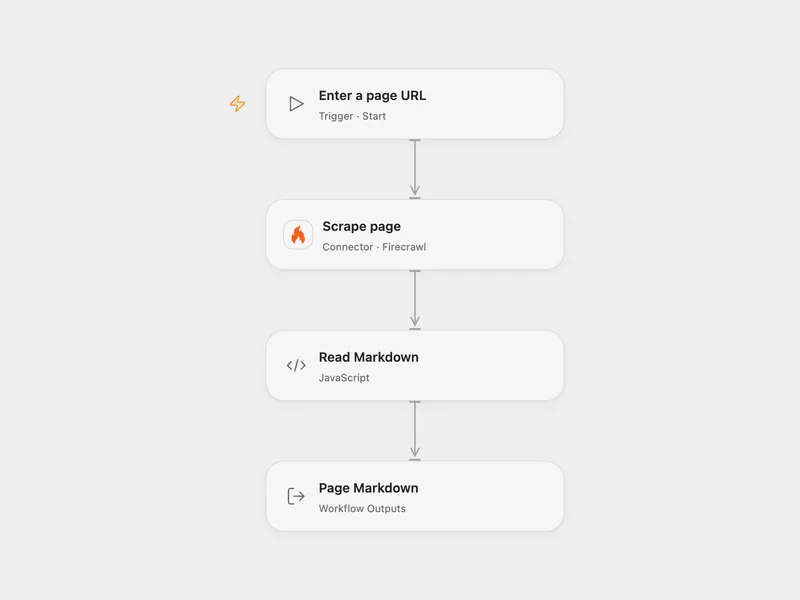
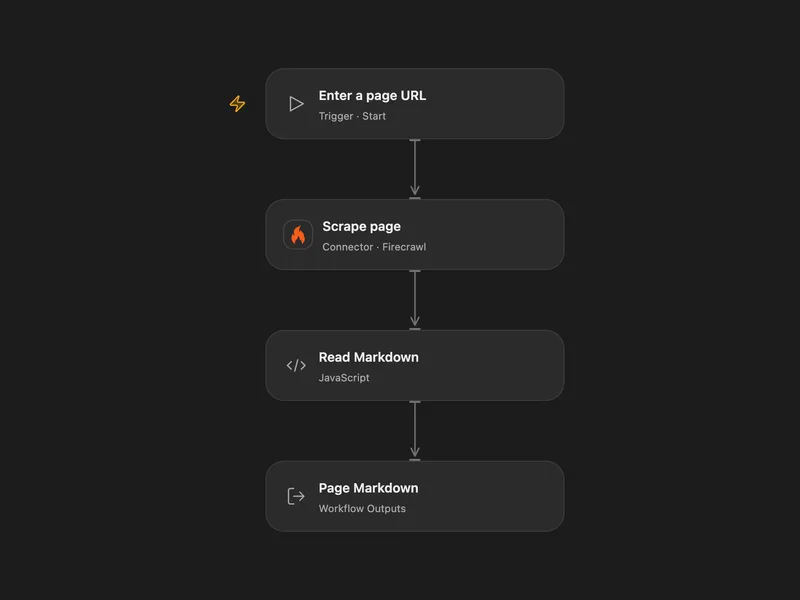
Scrape Page Markdown with Firecrawl
Call Firecrawl to scrape one page and return its Markdown.
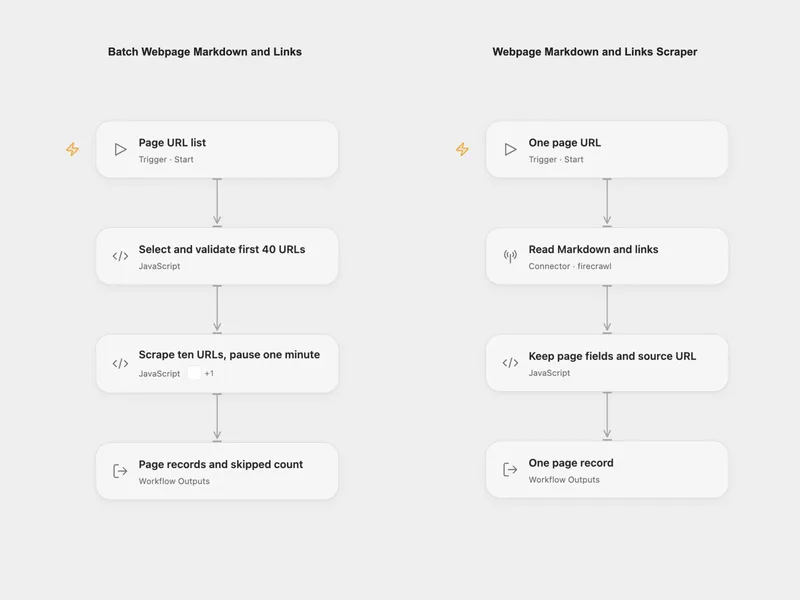
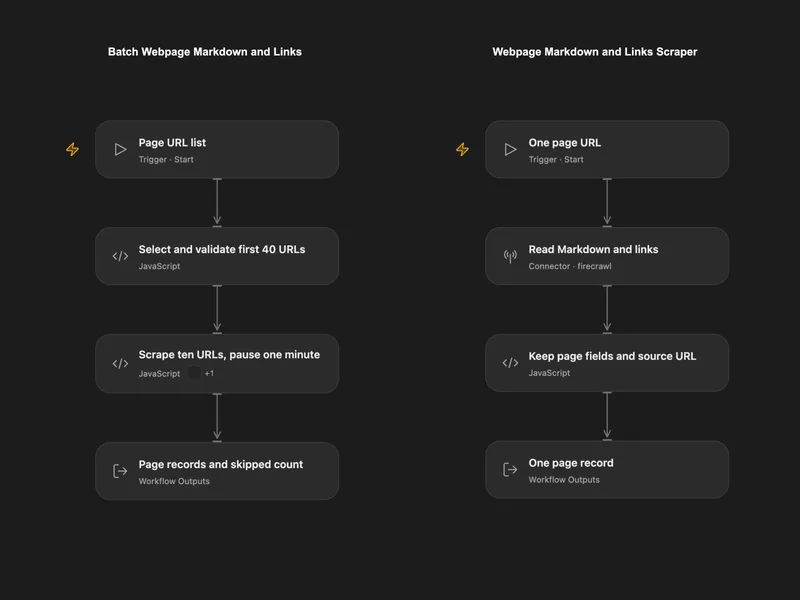
Batch Webpage Markdown and Links
Convert up to 40 page URLs into Markdown, metadata and link arrays, pausing one minute between groups of ten.
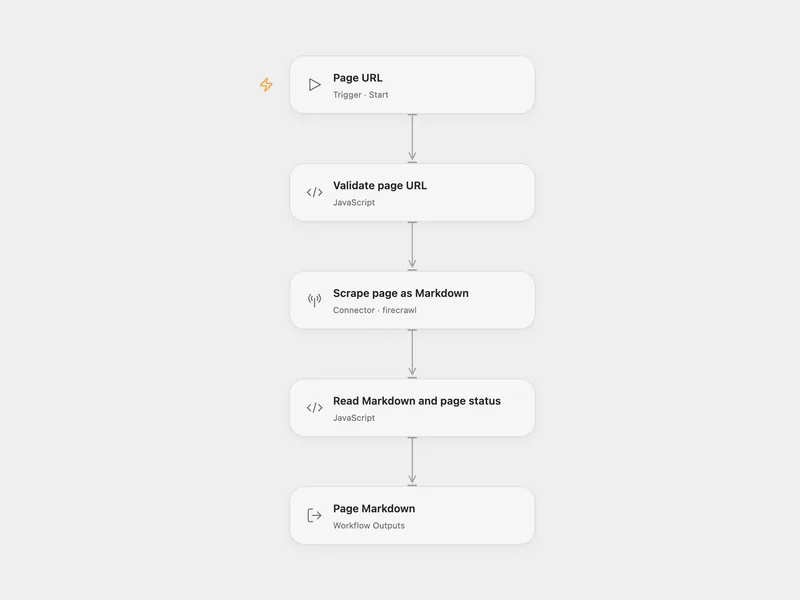
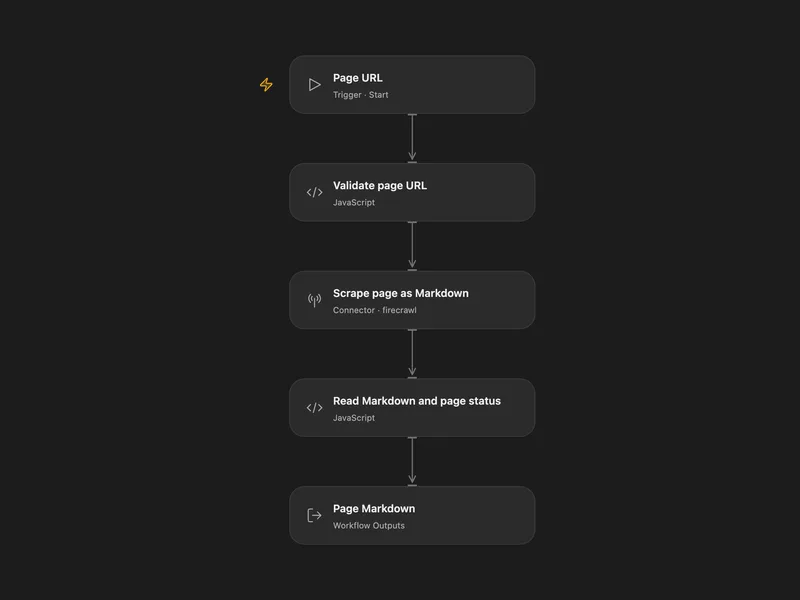
Webpage Markdown Extractor
Fetch one page through Firecrawl and return its Markdown content with the reported page status.
所有工具
Scrape Firecrawl
通过 Firecrawl 将一个 HTTPS 网页提取为 Markdown。AIsa 路由使用基础代理模式,不支持 PDF 网址。
aisa.scrape_firecrawlMap Firecrawl
通过 Firecrawl 发现网站链接。获取单个页面前,设置 limit 限制链接发现规模和用量。
aisa.map_firecrawlScrape
使用 Firecrawl 抓取 URL 或执行已启用的 Alexandria 提供方工具,并返回请求的输出格式。
firecrawl.scrapeMap Tavily
使用路径与域名筛选、抓取深度和自然语言指令发现网站链接。
aisa.map_tavilyExtract Tavily
通过 Tavily 提取已知网址的内容。检查 failed_results 中的单个网址失败;发现并抓取整个网站的页面可用 crawl_tavily。
aisa.extract_tavilyExtract Parallel
按目标和搜索词从最多 20 个网址提取相关片段或全文,保留部分结果和各网址错误。
aisa.extract_parallelJina Reader Read
读取并提取 URL 内容
fusion-api.jina_reader_read没有符合搜索条件的工具。