Firecrawl を Open Flow に接続
Turn a page or a web question into a concise answer with sources.
毎月 20,000 回のアプリ呼び出しが無料(有料サービスは別途課金)
アプリの説明と操作の詳細は英語で表示されます。
できること
Search the web, read selected pages, map sites, and collect content across multiple links. Specify freshness needs when cached material would not be suitable.
Search and Extract Pages
Search web sources, map site URLs, and extract content in selected formats.
Collect Multiple Pages
Submit batch or crawl jobs and retrieve their status and results.
Firecrawl を使うテンプレート
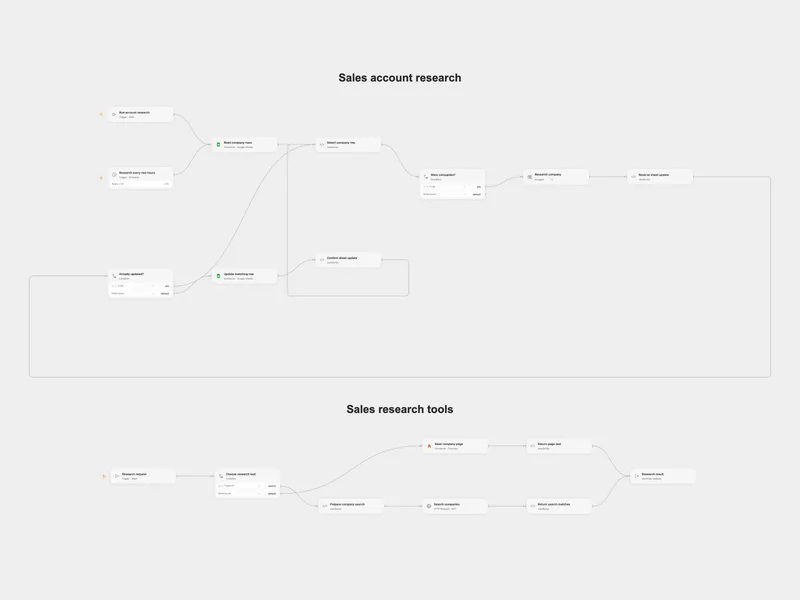
Research Sales Accounts in Google Sheets
Research companies on the web and update their matching spreadsheet rows.
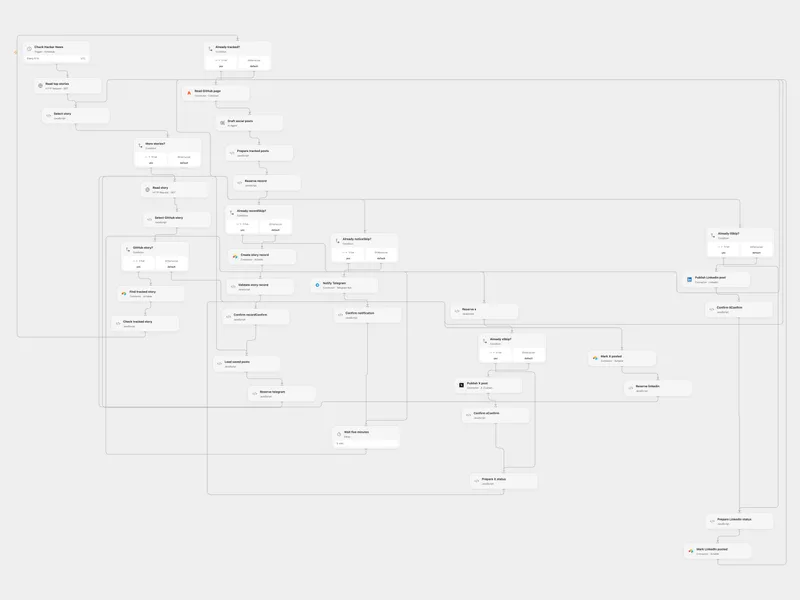
Amplify Hacker News GitHub Projects
Discover GitHub links on Hacker News, draft social posts and publish them after a short delay.
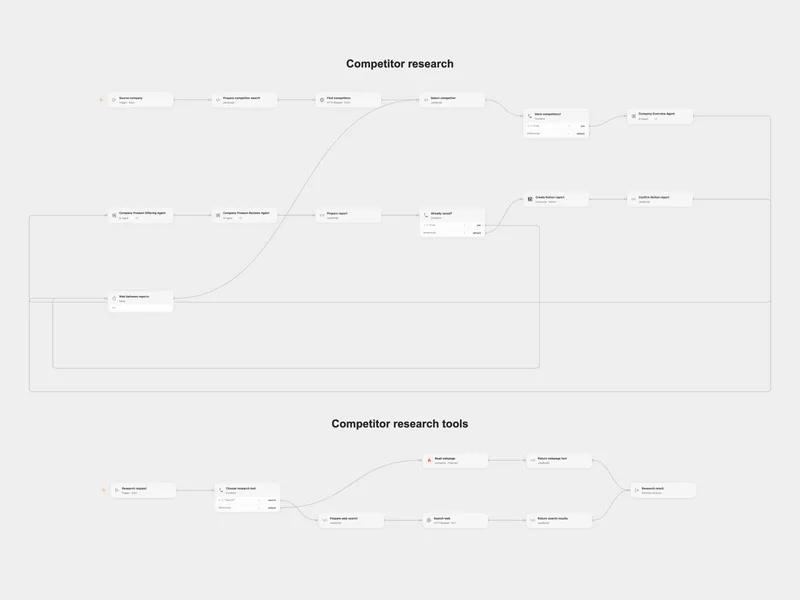
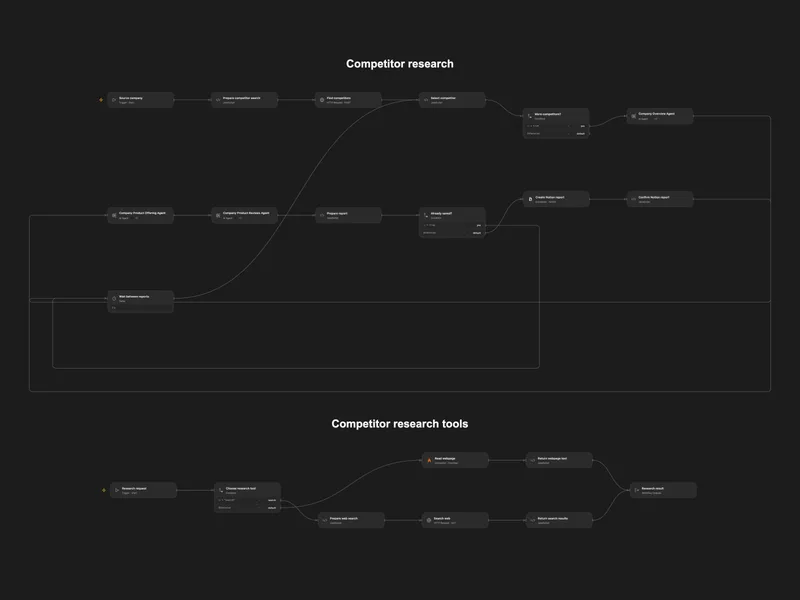
Research Competitors into Notion
Find competitors and research their company, products, and reviews in Notion.
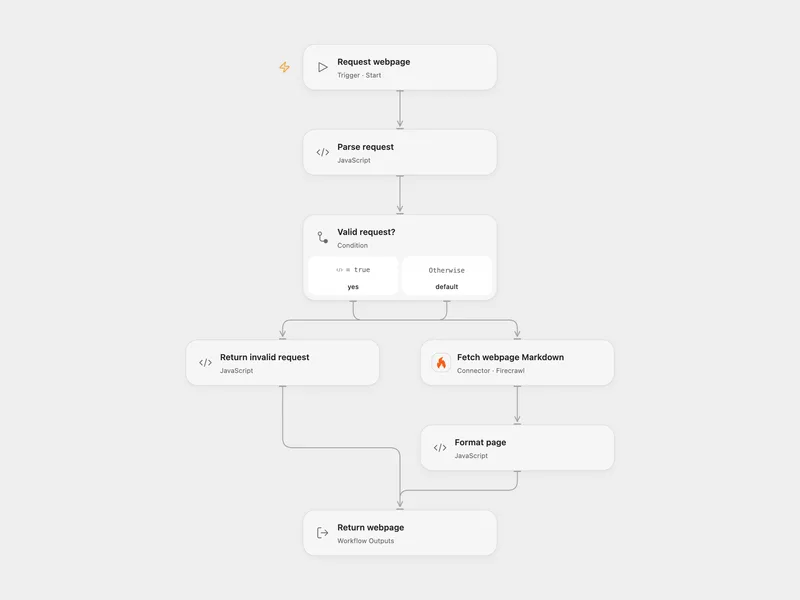
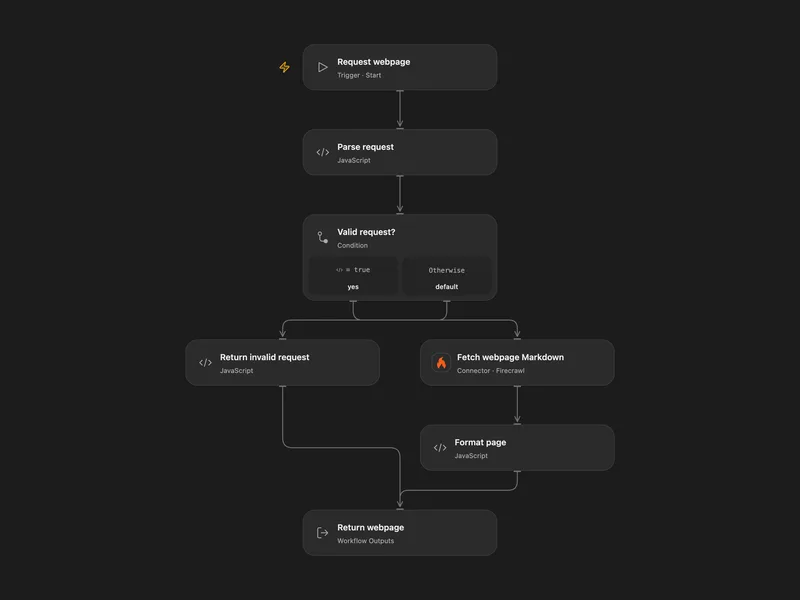
Fetch Webpage as Markdown
Fetch a webpage and return its Markdown content, optionally replacing links and image URLs.
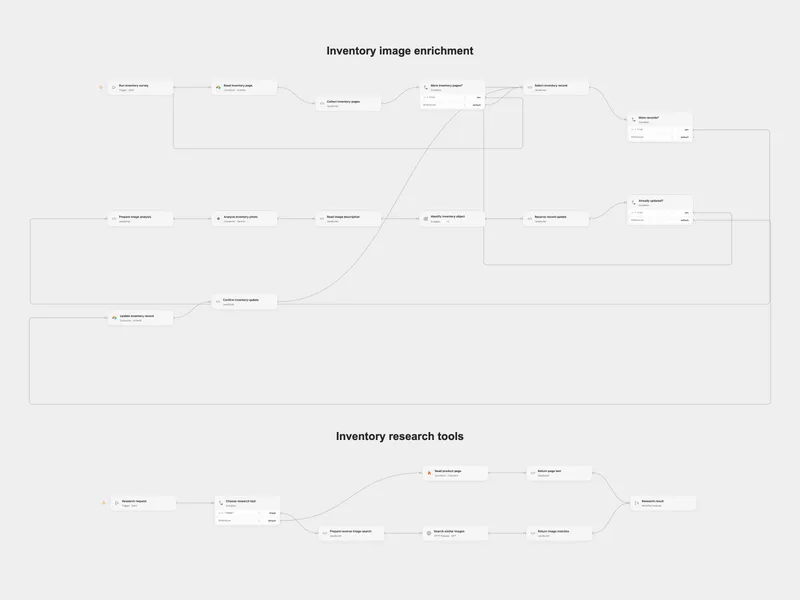
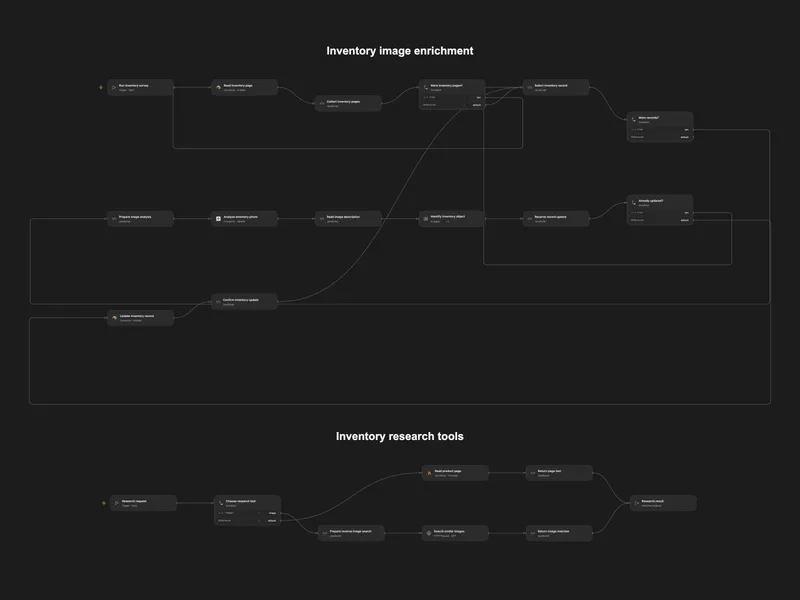
Enrich Property Inventory from Images
Analyze inventory photos and enrich Airtable records with product attributes.
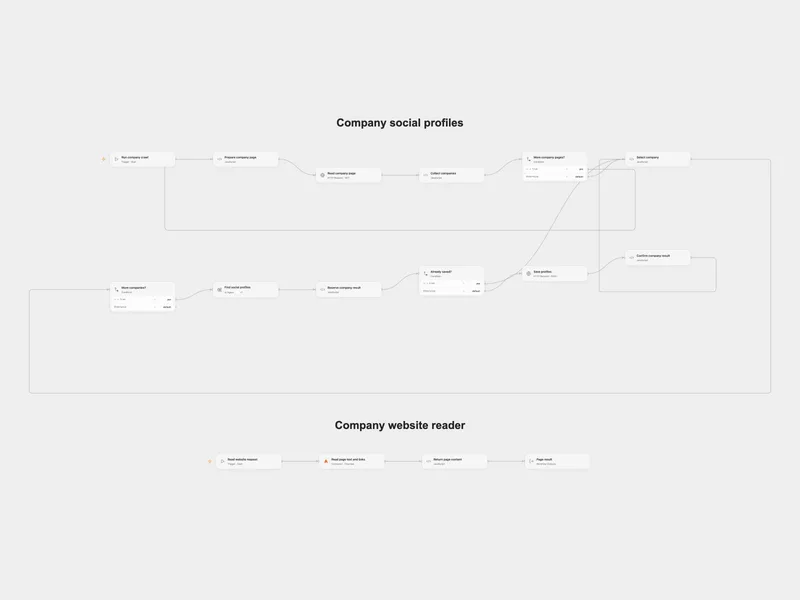
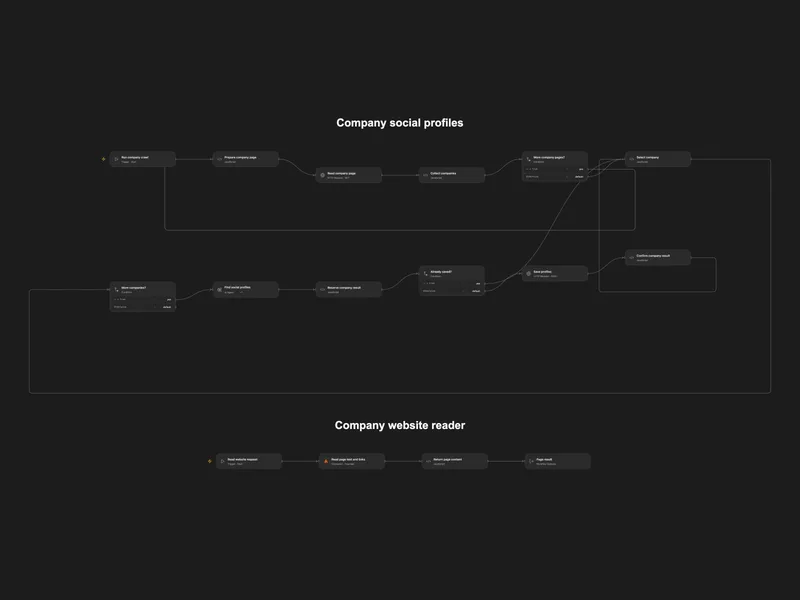
Crawl Company Social Profiles
Find company social profiles by exploring their websites and save the results to Supabase.
その他のテンプレート(5 件)
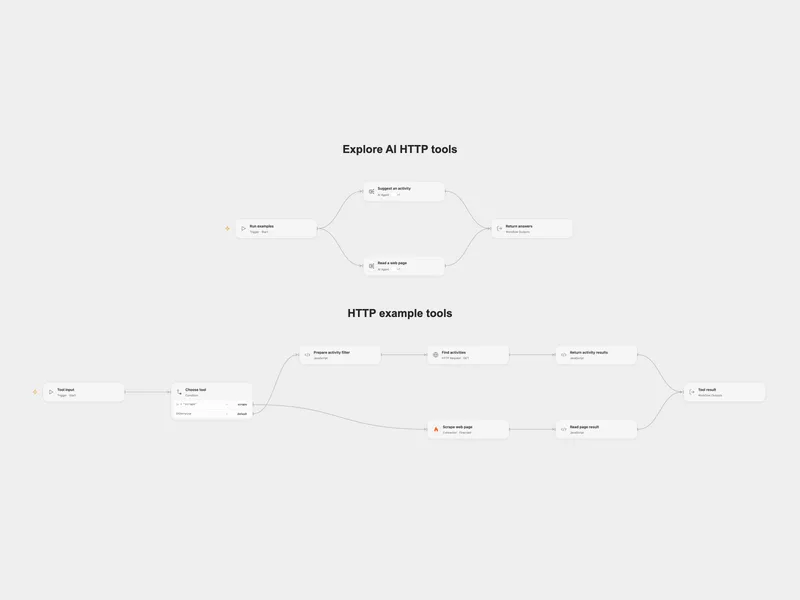
Explore AI HTTP Tools
Explore model-selected web scraping and activity search tools.
Enrich Airtable Inventory with Image Research
Research inventory images and update Airtable records with product attributes.
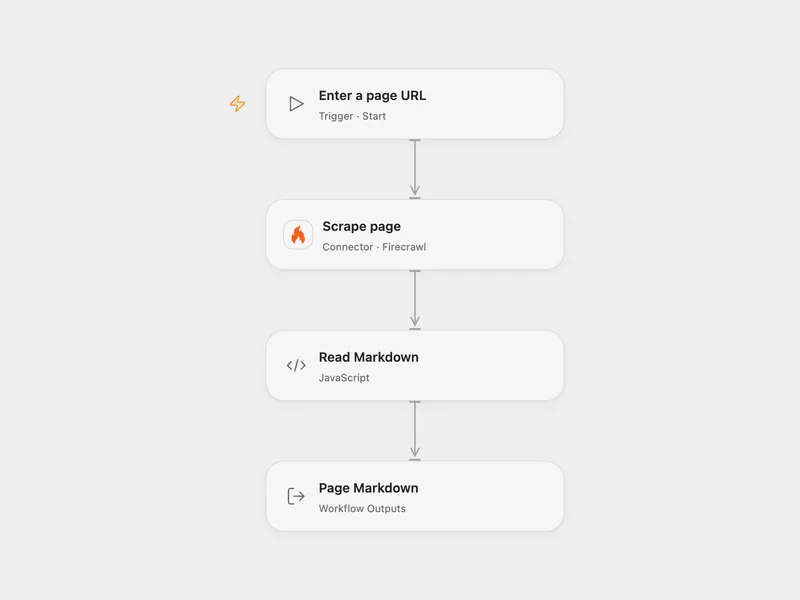
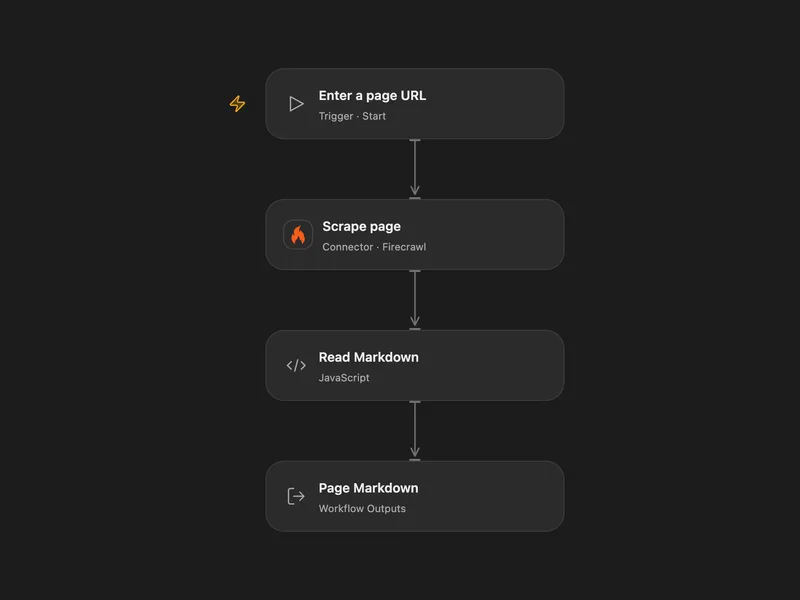
Scrape Page Markdown with Firecrawl
Call Firecrawl to scrape one page and return its Markdown.
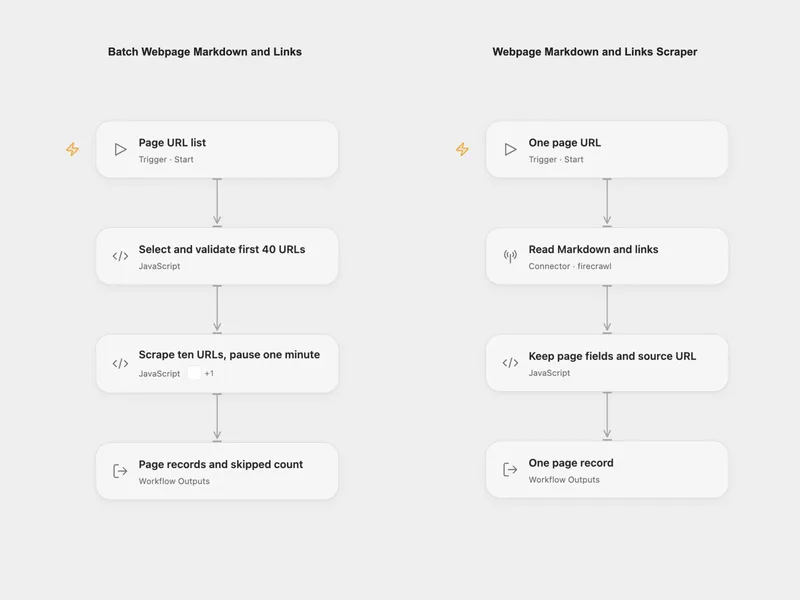
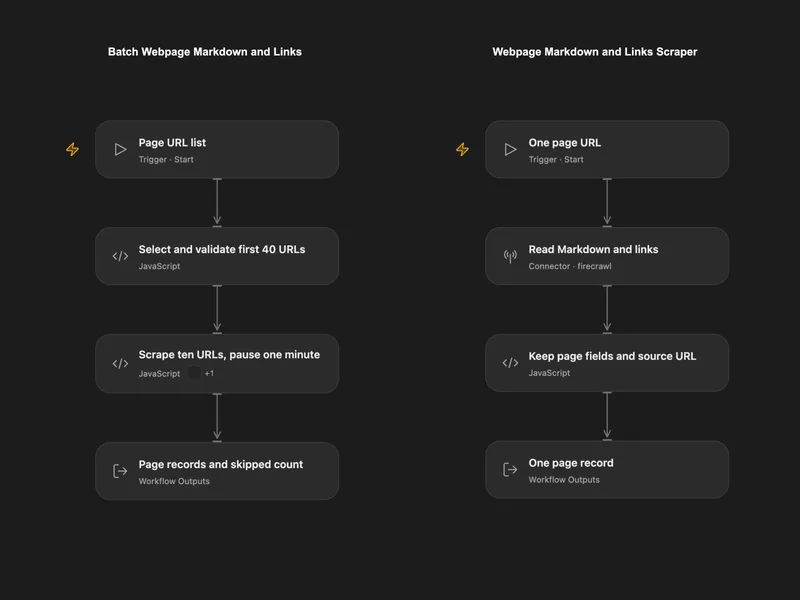
Batch Webpage Markdown and Links
Convert up to 40 page URLs into Markdown, metadata and link arrays, pausing one minute between groups of ten.
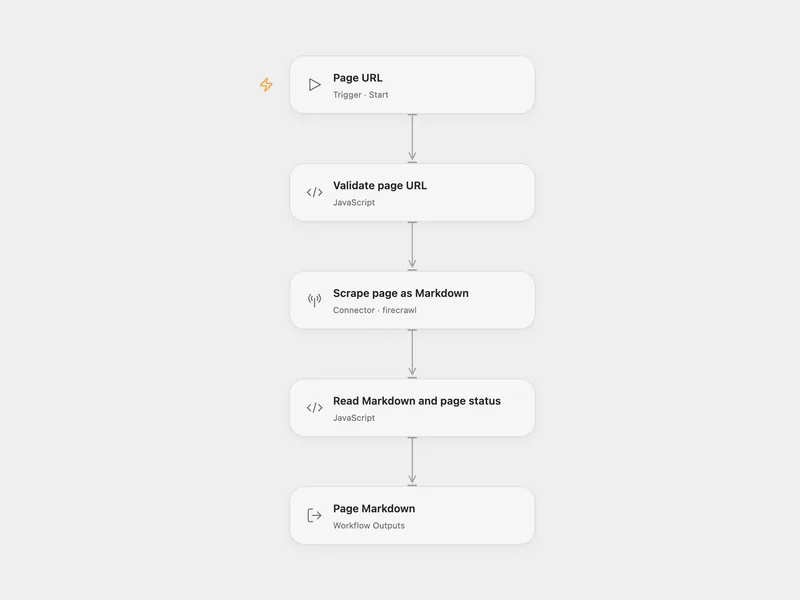
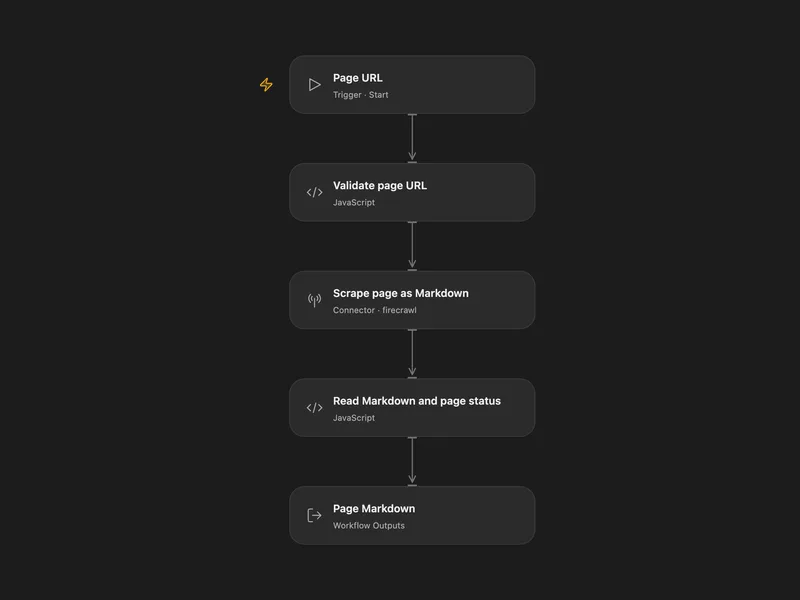
Webpage Markdown Extractor
Fetch one page through Firecrawl and return its Markdown content with the reported page status.
すべての操作
Scrape
Scrape a URL with Firecrawl or execute an enabled Alexandria provider tool and return the requested output formats.
firecrawl.scrapeBatch Scrape
Start a Firecrawl batch scrape job for multiple URLs and return the async job ID.
firecrawl.batch_scrapeBatch Scrape Get
Get the current status and paged results of a Firecrawl batch scrape job by job ID.
firecrawl.batch_scrape_getBatch Scrape Get Errors
Get the failed URLs and robots.txt blocks from a Firecrawl batch scrape job.
firecrawl.batch_scrape_get_errorsBatch Scrape Cancel
Cancel a running Firecrawl batch scrape job by job ID.
firecrawl.batch_scrape_cancelCrawl
Start a Firecrawl crawl job with compatibility fields accepted from legacy crawl inputs.
firecrawl.crawlCrawl V2
Start a Firecrawl crawl job with the official v2 crawl fields, including prompt-driven options generation.
firecrawl.crawl_v2Crawl Get
Get the current status and paged results of a Firecrawl crawl job by job ID.
firecrawl.crawl_getGet The Status Of A Crawl Job
Compatibility alias of crawl_get for the FIRECRAWL_GET_THE_STATUS_OF_A_CRAWL_JOB action name.
firecrawl.get_the_status_of_a_crawl_jobCrawl Get Errors
Get the failed URLs and robots.txt blocks from a Firecrawl crawl job.
firecrawl.crawl_get_errorsCrawl Cancel
Cancel a running Firecrawl crawl job by job ID.
firecrawl.crawl_cancelCrawl Delete
Compatibility alias of crawl_cancel for the FIRECRAWL_CRAWL_DELETE action name.
firecrawl.crawl_deleteCrawl List Active
List the currently active Firecrawl crawl jobs for the authenticated team.
firecrawl.crawl_list_activeCrawl Params Preview
Preview the crawl parameters that Firecrawl would infer from a URL and prompt before starting the crawl.
firecrawl.crawl_params_previewExtract
Start a Firecrawl extract job that returns structured data for one or more URLs.
firecrawl.extractExtract Get
Get the current status and output of a Firecrawl extract job by job ID.
firecrawl.extract_getSearch
Search the web with Firecrawl and optionally scrape the top results in the requested formats.
firecrawl.searchMap Multiple Urls Based On Options
Discover URLs from a website with Firecrawl's map endpoint using a legacy action name.
firecrawl.map_multiple_urls_based_on_optionsStart Agent
Start a Firecrawl agent job for multi-page autonomous browsing and extraction.
firecrawl.start_agentGet Agent Status
Get the current status and output of a Firecrawl agent job by job ID.
firecrawl.get_agent_statusAgent Cancel
Cancel a running Firecrawl agent job by job ID.
firecrawl.agent_cancelDeep Research
Start a Firecrawl deep research job. The Firecrawl agent researches the query and returns a markdown report with its sources.
firecrawl.deep_researchGet Deep Research Status
Get the current status and output of a Firecrawl deep research job by job ID.
firecrawl.get_deep_research_statusLlms Txt Generate
Start an LLMs.txt generation job for a website. Firecrawl maps the site and batch scrapes its pages; pass the returned url and urls to llms_txt_get along with the id.
firecrawl.llms_txt_generateLlms Txt Get
Get the current status and generated content of an LLMs.txt job by job ID.
firecrawl.llms_txt_getQueue Get
Get the authenticated Firecrawl team's queue status and concurrency information.
firecrawl.queue_getCredit Usage Get
Get the authenticated Firecrawl team's current credit usage summary.
firecrawl.credit_usage_getCredit Usage Get Historical
Get the authenticated Firecrawl team's historical credit usage summary.
firecrawl.credit_usage_get_historicalToken Usage Get
Get the authenticated Firecrawl team's current token usage summary.
firecrawl.token_usage_getToken Usage Get Historical
Get the authenticated Firecrawl team's historical token usage summary.
firecrawl.token_usage_get_historical検索条件に一致する操作はありません。
Firecrawl を Open Flow に接続
毎月 20,000 回のアプリ呼び出しが無料(有料サービスは別途課金)